Training images · Experimental dataset
Synthetic Webcam Scene Dataset
17,280 AI-generated webcam crops, organized into 12 scene categories. Original contact sheets, generation prompts and source-to-crop manifests included.
USD 99 One-time purchase · Images + source code
Checkout and digital delivery are handled by Payhip. The paid product includes both the image dataset and the source-code ZIP.
What is included in the purchase?
Category folders under train/ and val/, ready for your own dataset tooling.
The generated contact sheets behind the crops, with 60 originals per category.
The active category prompts used to request scenes, camera geometry and lighting variation.
Crop/source manifests, SHA-256 checksums, extraction settings and a dataset card.
Source code included: a companion ZIP for grid extraction, training, ONNX export and a C++/OpenCV reference wrapper. Both ZIPs are delivered with the USD 99 product.
The originals and crops show the same underlying scenes. The 240-image sample is part of the full collection. Neither should be counted as additional independent training examples.
Look at the images before deciding
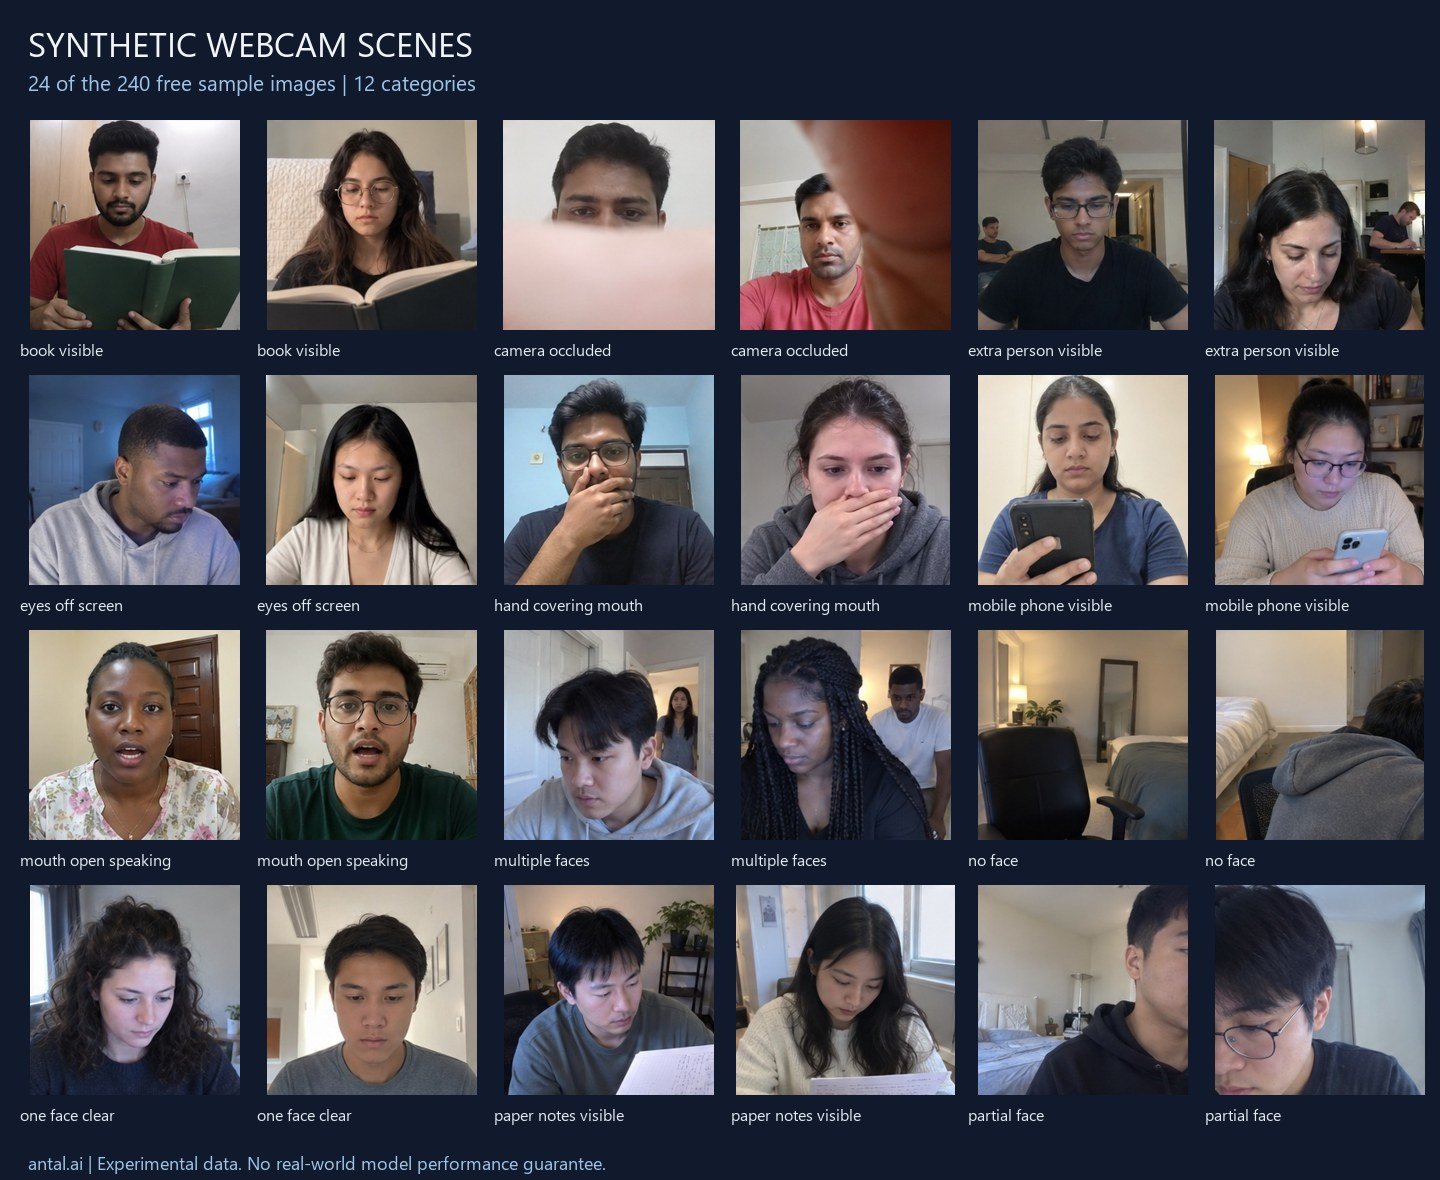
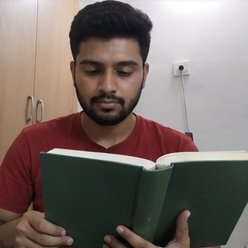
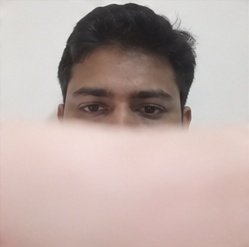
One example from each category is shown below. Open an image to inspect its original crop size. These are generated scenes, not photographs supplied by real exam participants.
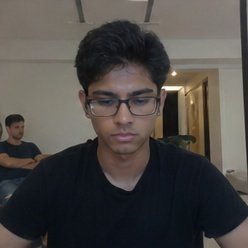
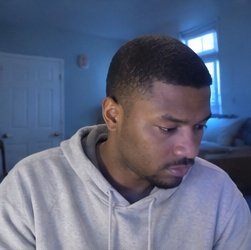
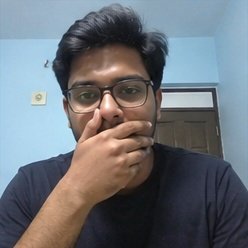
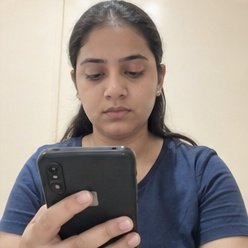
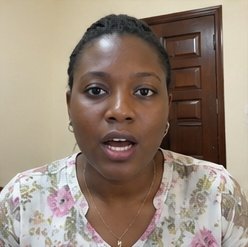
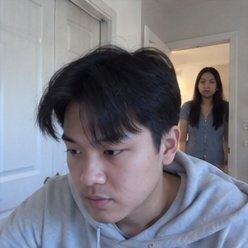
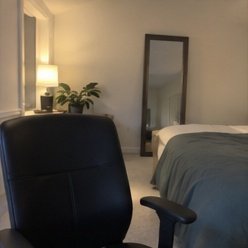
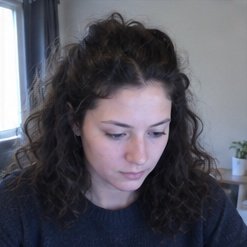
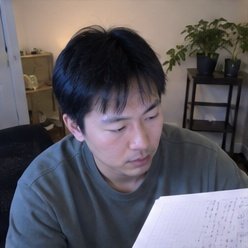
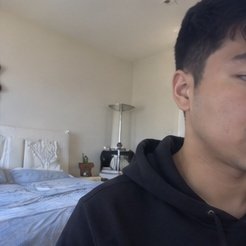
The free sample ZIP contains 240 JPEGs: 20 per category, from 240 distinct source sheets. It includes a sample manifest and is approximately 5.08 MB. It is an inspection sample, not an independent benchmark or a prebuilt train/validation set.
Twelve categories, with explicit limits
| Folder label | Intended visual content | Crops |
|---|---|---|
book_visible | A book visible in the scene | 1,440 |
camera_occluded | An obstructed camera view | 1,446 |
extra_person_visible | An additional person in the scene | 1,440 |
eyes_off_screen | A subject depicted looking away | 1,440 |
hand_covering_mouth | A hand covering the mouth | 1,440 |
mobile_phone_visible | A visible mobile phone | 1,440 |
mouth_open_speaking | An open mouth / speech-like pose | 1,440 |
multiple_faces | Multiple visible faces | 1,428 |
no_face | No visible face | 1,446 |
one_face_clear | A clear single face / intended normal state | 1,440 |
paper_notes_visible | Visible paper notes | 1,440 |
partial_face | A partly visible or cropped face | 1,440 |
| Total | 12 categories | 17,280 |
Labels come from the intended generation category. They are not exhaustive manual annotations of every object or event. Some concepts overlap; a still image cannot establish speech, a precise gaze target or misconduct.
Formats, dimensions and split
- Originals: 719 PNGs at 1536 × 1024 px and one at 1535 × 1024 px.
- Crops: RGB JPEGs, 216–375 px wide and 184–287 px high. Sizes vary; they are not native 224 × 224 images.
- Supplied split: 12,096 train / 5,184 validation crops.
- Full image ZIP: 1.99 GB (1,992,514,453 bytes). The archive includes metadata as well as the images.
- Annotation scope: category folders and crop locations within source sheets. No object boxes, segmentation masks, landmarks, demographic labels, complete multilabel annotations, audio or video.
originals/<category>/<source>.png
images/train/<category>/<crop>.jpg
images/val/<category>/<crop>.jpg
metadata/crops.csv
metadata/sources.csv
metadata/dataset-audit.json
metadata/checksums.sha256
prompts/generation-prompts.md
DATASET_CARD.md
Generated entirely from text prompts
I generated the source sheets in Picsart Pro using the option labelled “GPT Image 2.5.” That is the service label I recorded, not an independently verified underlying model version. I supplied text prompts only and uploaded no real-person reference photographs.
The prompts requested 6 × 4 grids of webcam scenes. Five sheets had a different number of cells. Labels, anatomy and scene details can be imperfect; demographic balance, unique identities and absence of near-duplicate scenes have not been established.
The historical prompt book also has a blurry_or_compressed template. There are no images for that category in this dataset.
Where this collection can be useful
A concrete starting point for dataset-loader tests, training-pipeline prototypes, synthetic-to-real experiments, relabeling exercises and studying generator artifacts. The value is the existing collection, its organization and traceability; whether it improves your model is something to measure.
This is a self-service project snapshot. It does not include installation help, retraining, integration work, custom development, promised updates or a model-performance guarantee. Read the support policy.
Package availability
240-image sample
20 images per category, with a manifest and documentation. Get the free sample through Payhip; no source code is included.
Get the free sample on PayhipComplete image dataset · USD 99
All crops, original sheets, 12 prompts, provenance records and the companion source-code ZIP. Read the dataset and source-code license terms.
Buy dataset + source · USD 99The source-code ZIP is included in the USD 99 purchase as a companion download. The free preview contains only the 240-image sample and its documentation. There are no trained model files in the sample, source or full image archive.